Part 1 of an ongoing project journal
From a personal experiment toward a system people may depend on. AI-generated illustration.
A personal AI project of mine has just been approved for a controlled staff pilot in a healthcare division.
That sounds like a fairly neat progression. Have an idea, build something, show it to the right person, get the green light.
The actual story includes years of conversations with a friend, a growing collection of AI subscriptions, and about six months of experimentation before a viable first demo. My graduate coursework helped shape and document the idea along the way. And there were a surprising number of decisions about everything surrounding the AI.
Which model should do which job? How much information should it receive? What happens when a document changes? Who checks the answer? Who can access the system? How do I know a code change hasn't broken something that worked yesterday?
Somewhere along the way, this started looking very familiar to someone who works in IT.
There was also a lot of thinking about processes.
Especially processes.
If you are trying to figure out where AI fits into your work, that may be the most useful place to start.
The playing around mattered
My buddy Rich and I have been talking about AI since around 2012. Long before there was a chatbot subscription on my credit card statement, we were discussing what these machines might eventually do and how they might change our lives and our work.
When ChatGPT subscriptions became available, we both subscribed and started playing with it.
I mean that in the best possible way. We asked questions, tried ideas, compared experiences, and thought about where this could be useful. Some experiments went somewhere. Others helped us understand the limitations.
Over time, my toolkit grew to include Codex, Cursor, Gemini, Lovable.dev, Base44, Instinct, and Muse. I was also taking training and working on AI certifications. There was plenty to learn, and there still is.
This was personal exploration, outside work, using my own time and AI subscriptions. It also became part of my graduate coursework. I wanted to understand what I could actually build and how I could become better at applying these tools.
My goal is to be the IT professional who can take a business problem, understand the process behind it, and apply an AI solution where it makes sense. That involves infrastructure, security, governance, and oversight as much as it involves a model.
The tools are interesting. Getting something useful to work reliably is what keeps my attention.
The master's program helped give it shape
My Executive Master's in Technology Management at Columbia University had a big impact on how this project developed. I completed the program in 2026.
I used the project for assignments in several of my classes, adapting it to each class's requirements and approach. That meant the idea was being conceptualized and documented during the program while I continued experimenting with the technology.
Working with the same underlying idea across different assignments gave me opportunities to revisit it from different angles. I had to explain what I was proposing and develop the thinking around it, as well as work on the implementation.
That helped connect the technical exploration to the management questions that keep coming up in this project: What business problem does it address? How does it fit the process? What would useful results look like? How should it be governed and operated?
Those questions are central to the kind of AI engineer I want to become. I want to be able to make the case for a solution, document it, and understand the responsibilities involved in putting it to use.
The project was taking shape through both personal experimentation and formal study. By the time I introduced the SOP assistant use case to the division, there was already a body of thinking and documentation behind the idea. That foundation continues to influence how I approach the controlled pilot.
A chatbot that knows where to look
One approach that kept coming back in my experiments was retrieval-augmented generation, usually shortened to RAG.
The basic idea is approachable. Imagine asking a general-purpose AI assistant a question about your organization's procedures. It might know a great deal about the general subject. It also needs the organization's current, approved procedure to answer the actual question.
With RAG, the application first searches a defined collection of documents for relevant material. It then gives that material to the model to help produce a response, with references back to the sources.
Think of it as giving the assistant the relevant pages before asking it to help. The model does not have to be retrained every time a procedure changes; the document collection and its search index need to be maintained.
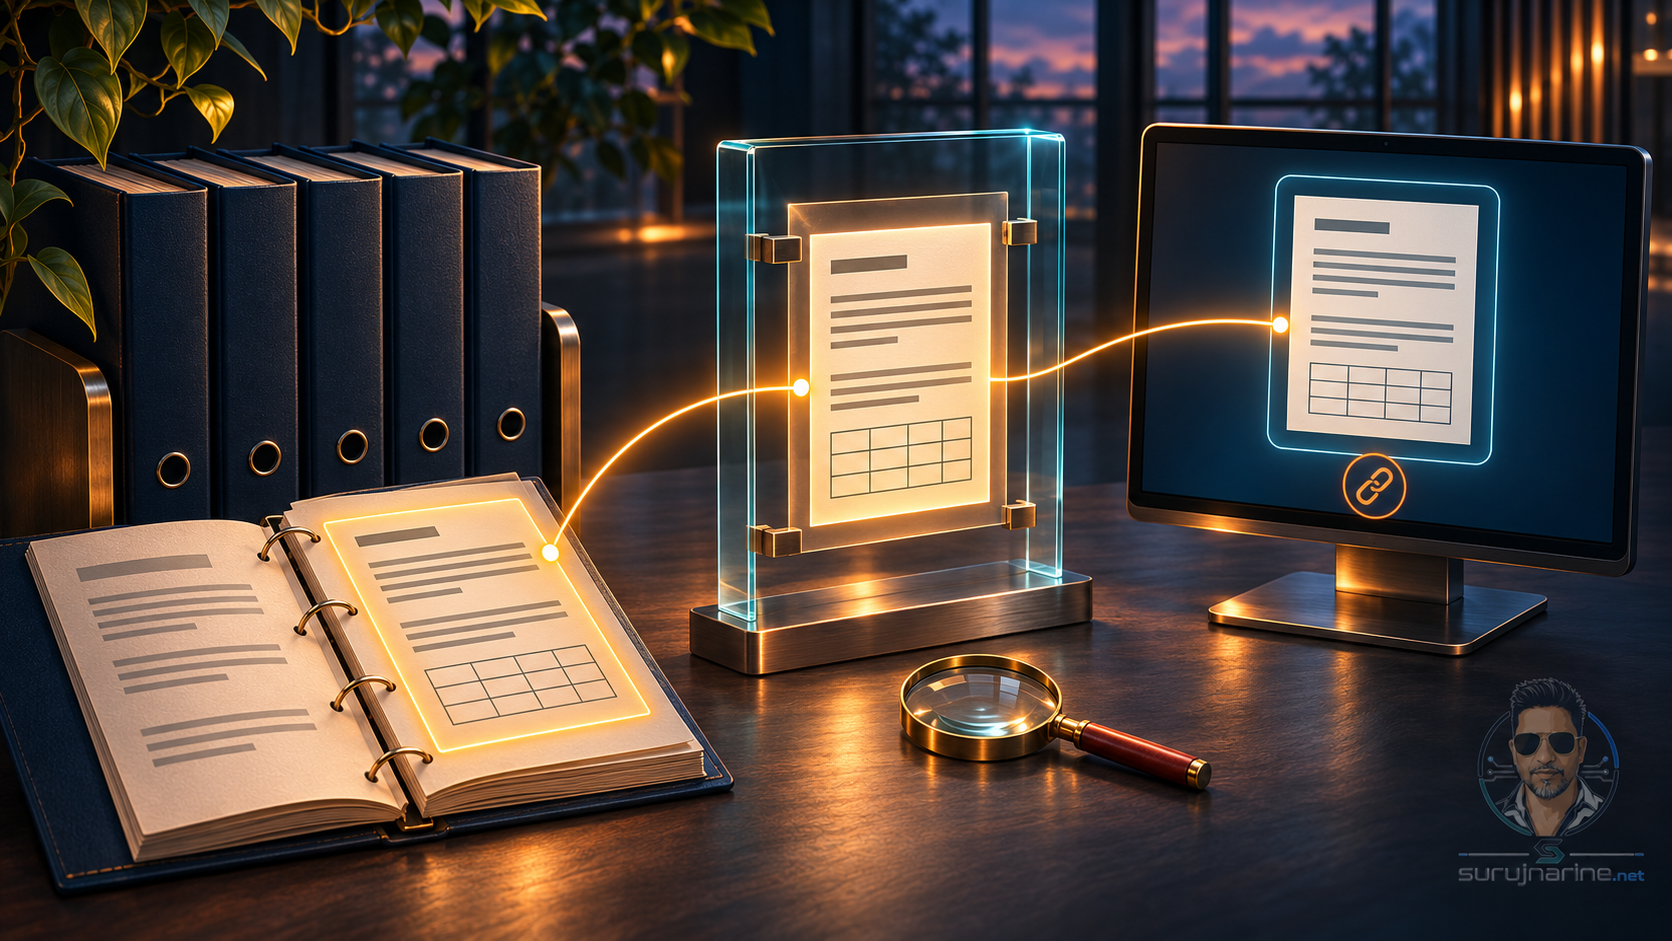
Find the relevant source, inspect it, and keep the reference attached. References still need to be checked. AI-generated illustration.
That does not automatically make the response correct. The system still has to find the right document, use the right version, interpret the question properly, and handle missing or conflicting information. An impressive answer with the wrong source is still a wrong answer.
What interested me was how widely this pattern could apply. Organizations already have procedures, policies, manuals, and other information that people need throughout the day. The information may exist and still take effort to find.
Helping someone reach the right approved information seemed like a useful problem to work on.
The use case became an SOP assistant
The first use case I introduced to a division at my job was an AI assistant for standard operating procedures, or SOPs.
The idea is straightforward: a staff member asks a question, the assistant finds supporting material in the approved procedures, and the response includes references so the staff member can inspect the source.
For this implementation, I have taken a deliberately constrained approach. The model helps select and review evidence, while the assistant displays complete, unedited extracted source pages with references. It does not rewrite clinical instructions into a new set of steps. If the evidence is insufficient or the checks fail, it withholds the answer.
Even that needs testing. A PDF can look perfectly clear to a person while its extracted text loses the relationship between a table heading and a value. A relevant page can still be incomplete evidence. A reference proves where text came from; someone still has to establish whether it supports the question.
Document management also became part of the engineering. The newest file needs to be checked against the approved version. Changed or withdrawn material needs to be handled, and the references need to identify the version actually used.
There are permissions to consider before expanding the library, too. Internal access and a paid reference subscription each come with terms that need checking before incorporating material into an AI workflow.
A lot of useful RAG work happens before the model receives anything.
Six months to a viable demo, and a lot of small lessons
It took roughly six months of experimentation to reach a first demo that made me feel the approach was viable.
That was a learning period: trying tools, working through ideas, and learning what the surrounding infrastructure needed to do. The conceptual work and documentation developed through my coursework were another part of the project's foundation. I then started going deeper into options such as Amazon Bedrock and local models.
The assistant's runtime is being built around Amazon Bedrock in an organization-controlled AWS environment. My personal subscriptions supported my learning and development work; the deployed assistant needs its own managed runtime and controls.
Along the way, I started paying much more attention to the job I was assigning to each model.
Some tasks need deeper reasoning. Others need speed, a predictable response format, or a lower operating cost. A model that helps me reason through an architecture decision still needs to be evaluated separately for evidence selection in a document assistant.
The useful comparison is on representative tasks: Did it find the correct evidence? Was anything important missing? Did it appropriately decline an unsupported question? How long did it take, and what did the completed task cost?
I am preparing that kind of reviewed comparison for the SOP assistant. I do not yet have clinical pilot results that establish a winning model.
I also learned to ask whether a particular step needs a model at all. A question such as “Who approved SOP01?” may call for a direct lookup of the document-control section. We have added targeted retrieval for that kind of question, with source verification and evidence review still required. Making a model search harder would miss the opportunity to improve the retrieval process itself.
Then there is token use.
Tokens are small units of text that models process. Many services price usage around input and output tokens, and the amount of context also affects what can fit into a request. Long conversations, repeated instructions, unnecessary document text, retries, and multiple agents repeating the same investigation can all consume the budget.
The goal is to give the model enough relevant context to do the job well. For an SOP question, removing an exception to save a little money would be a terrible optimization. Focused retrieval, reusing unchanged document embeddings, and avoiding duplicate work are more useful places to look.
I want to understand the cost of a correct, completed task, including the checks and retries it took to get there.
Guardrails have to be part of the application
“Only use the approved documents” sounds like a sensible instruction. I still need the application to enforce what the model can actually read, return, or do.
For this assistant, that includes access checks before source retrieval, constrained response formats, validation of selected source identifiers, version checks, and withholding evidence when required checks fail. The model cannot grant itself permission to read a restricted document or approve a clinical release.
Prompt injection adds another consideration. A user message, retrieved document, or external page can contain text that tries to redirect the model's behavior. A passage inside a document might look like an instruction to disregard the application's rules. It still needs to be treated as source content, with no authority to change those rules.
OWASP's guidance describes layered defenses, including separating instructions from untrusted content, validating outputs, limiting tool permissions, and requiring human approval for consequential actions.
That has practical consequences for how I build. I need to test attempts to cross those boundaries, keep permissions narrow, and validate what comes back before the application uses it. A provider's filtering features are another capability to evaluate and configure; using its model does not establish that every protection is switched on.
I also need to keep testing the limits of these controls. Passing a few adversarial examples would give me evidence about those examples, not proof that prompt injection has been solved.
Healthcare makes the whole data path matter
Healthcare brings the privacy and security questions into sharp focus.
I have to understand what information enters the workflow, where it travels, who can access it, what gets stored, and what appears in logs or backups. Credentials belong in protected configuration. Troubleshooting should not become a reason to collect sensitive material unnecessarily.
HIPAA compliance has to be considered across that workflow. Where a cloud service creates, receives, maintains, or transmits electronic protected health information on behalf of a covered entity or business associate, appropriate business associate agreements and the organization's own risk analysis and safeguards matter. HHS's cloud-computing guidance explains those responsibilities.
A service's eligibility for healthcare workloads still leaves work to do on the application's configuration, access, operating procedures, and institutional review. I cannot turn a model choice into a claim that the whole project has completed that review.
The SOP assistant is intended for questions without patient information. That needs to be clear in the interface and in testing; the contents of the document library alone do not determine what a user might type into a question.
I am keeping personal learning tools and subscriptions distinct from the managed environment intended for organizational use. The controlled pilot approval is also distinct from privacy, security, and clinical acceptance.
These are part of designing a healthcare tool responsibly from the beginning.
AI-generated code needs a software lifecycle
Another set of lessons involved the code itself.
AI tools can help me produce changes quickly. I still have to understand those changes, review them, test them, and know how to recover if something goes wrong.
That brings me back to version control, small reviewable changes, dependency management, protected secrets, and separate development and production environments. When several agents contribute, I also need clear ownership of files and a way to bring their work together without silently overwriting changes.
CI/CD stands for continuous integration and continuous delivery or deployment. The useful principle here is having a repeatable path from a proposed change through checks to a release, with the appropriate approvals along the way. In this project, automated checks support controlled promotion; publishing a code change does not grant clinical approval.
The tests need to cover more than a successful demonstration. I want to know what happens with a missing document, an expired session, a changed source, an unsupported question, a service timeout, or a failed audit write. The application needs a defined failure response instead of improvising an answer to keep the conversation moving.
The AI parts belong in change management too. A different model, a revised instruction, a new retrieval setting, or a changed document can alter the behavior without a visible redesign of the screen. Their versions and evaluation results need to travel with the release.
I also need enough operational visibility to investigate a problem: which version was running, which evidence it used, where a request failed, how long it took, and what it cost. Collecting that information while keeping raw questions and sensitive source text out of routine logs is part of the design.
Recovery matters as well. I want a controlled way to restore an earlier release or stop serving questionable material while it is reviewed.
All of this is familiar software and operations work. AI gives it a few more moving parts.
Learning to manage the agents
As my use of AI tools has grown, I have become increasingly interested in directing their work.
I want to be the manager of agents, the conductor keeping the work moving toward a useful outcome.
There is a useful comparison with managing human employees. People have different strengths, and a good assignment takes those strengths into account. It also gives them a clear objective, relevant context, boundaries, and a definition of what a satisfactory result looks like.
I am learning to bring the same discipline to agents. A research task, an implementation task, a design review, and a test investigation may need different capabilities. Giving every agent the same vague request mostly creates more output for me to reconcile.
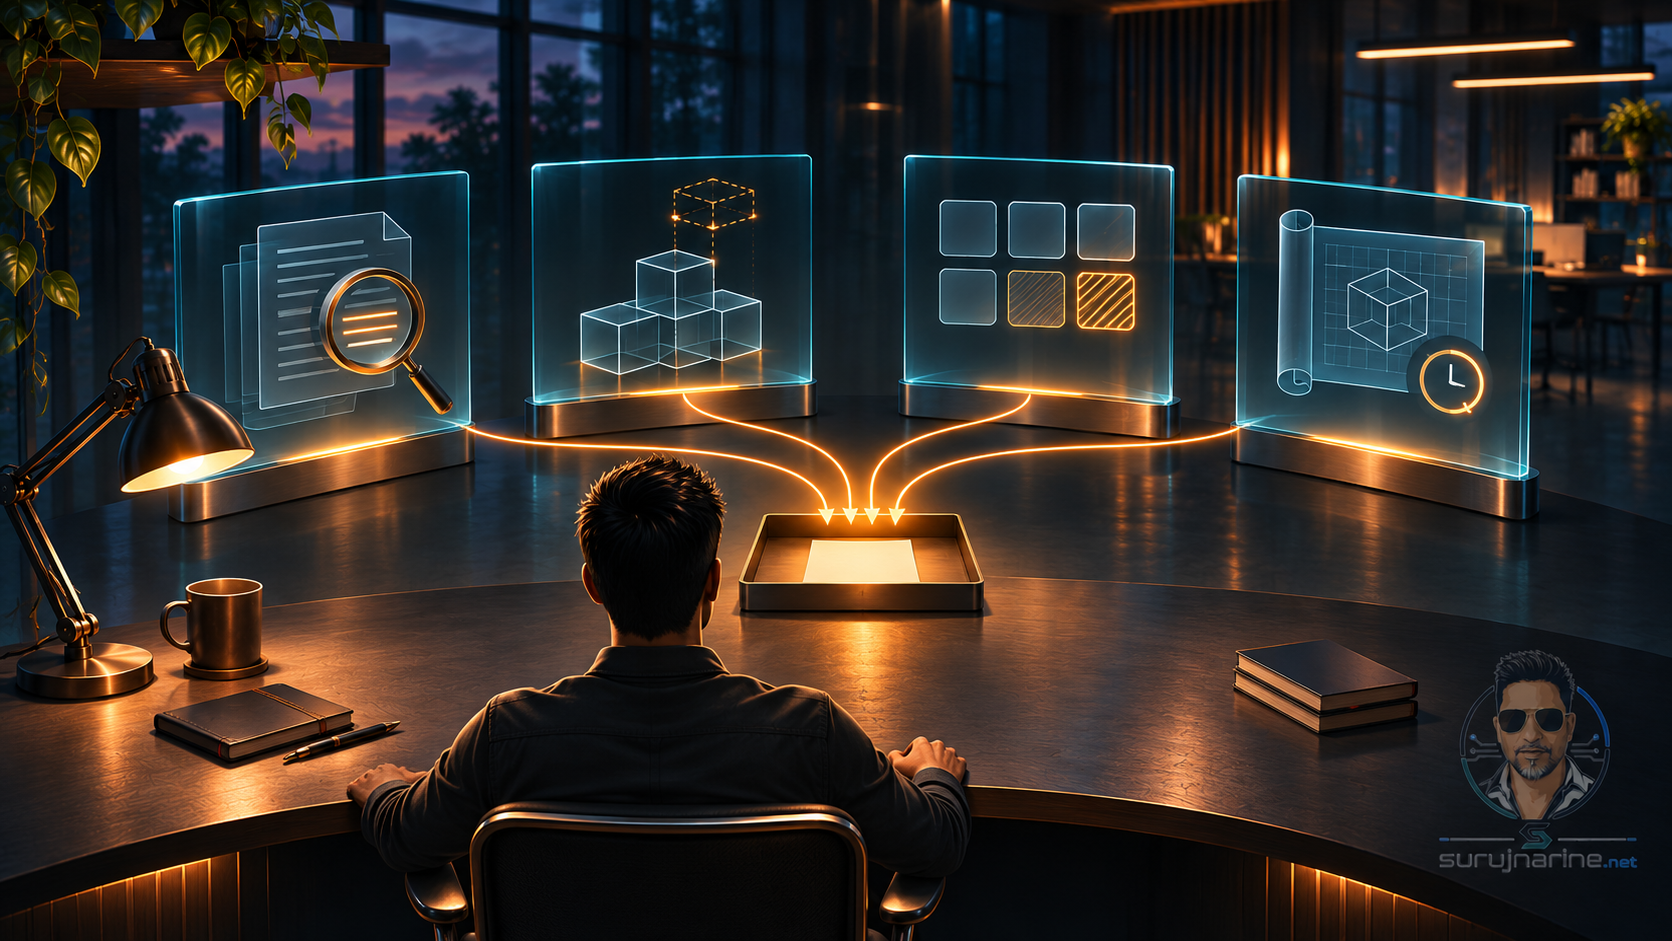
Specialized agents can share the work. A person still sets direction, reviews the results, and takes responsibility. AI-generated illustration.
A better brief might ask an agent to inspect a specific access-control change, identify how an unauthorized request could get through, and report the evidence. That gives me something concrete to assess.
Independent work can happen in parallel, but dependencies and handoffs need managing. Two agents editing the same files can create integration work. Repeating the entire project history for every small task uses context and tokens. Repository instructions, clear task boundaries, and concise handoffs help keep the work coordinated.
Review needs care too. Having another agent examine a change can expose problems, but several agents may share the same mistaken assumption. Agreement among them does not establish correctness or replace the expertise needed for a consequential decision.
I still need to understand what changed, why it changed, what evidence supports it, and what remains unverified. The agents do useful work; responsibility for integrating and accepting it stays with the people running the project.
That is a direction I want to develop in professionally: an AI engineer who can connect the tools to business objectives and processes, with the governance and operational discipline needed to make the result useful.
An email turned it into a pilot
I emailed the division head to introduce the project and describe the SOP assistant use case. He is open to innovation, and his reaction was enthusiastic.
The conversation quickly moved toward practical questions: how staff would access it, whether it could stay readily available on their computers, and how a pilot could begin.
I appreciated those questions. They bring the discussion directly into the working day. A tool can have a strong technical design and still be inconvenient enough that people rarely use it.
The project now has approval to move forward with a controlled staff pilot. We still need to evaluate its accuracy, usefulness, access controls, and fit with the team's work before it can become production clinical tooling.
The plan is to start with a focused use case, get knowledgeable staff involved in testing, and improve it using their feedback. A web interface and a Windows tray companion are part of making access convenient, subject to the appropriate staff sign-in and security controls.
Human involvement is essential here. The people who know the procedures need to assess the evidence and the situations in which the assistant should withhold a response. High-risk or consequential decisions need a qualified person with the authority, context, and time to review them.
“Human in the loop” needs to describe an actual workflow. Who reviews? At what point? What can they inspect? Can they stop the action or reject the result? Where is that decision recorded?
For the SOP assistant, reviewed source extraction, acceptance cases, evaluation, and final clinical sign-off are separate requirements. A second model reviewing the first model's selection does not satisfy them. The assistant is also not being given authority to make patient-specific clinical decisions.
That is why the controlled pilot matters. It gives us a way to learn with the right people involved before asking the tool to carry more responsibility.
Please understand the process first
I am optimistic about what AI can do for businesses and society. I also think the current hype makes it too easy to skip some basic questions.
What problem are we solving? Who has it? How is the work done today? Is that process clearly defined? Does it need to exist in its current form?
Putting AI into a bad process may give you a faster bad process. Automating an unnecessary process can be an efficient way to keep doing something nobody needed. We already know how to do that without AI. lol.
My interest has always been in process improvement and automation. AI expands what I can attempt, but it does not remove the need to understand the business, define the workflow, or decide what a good result looks like.
For this pilot, useful measures could include whether staff find the correct evidence, whether the references are complete, how often the assistant appropriately withholds an answer, how long a task takes, and whether staff find the tool worth using. Latency and operating cost matter too.
An assistant that refuses everything might avoid unsupported answers while providing little practical help. An assistant that answers everything needs close scrutiny. The evaluation has to examine both usefulness and appropriate boundaries.
Those are things we need to measure. I do not yet have pilot results or a productivity claim to share.
I would rather document what we learn than announce a percentage improvement before anyone has tested it.
Where I would start today
If you are new to AI, this may sound like a lot. You do not need to master all of it before your first experiment.
Start with a small task you understand well and can check yourself. Use non-sensitive material you are permitted to use. Write down how you do the task today and what improvement would be valuable.
Then try the tool, inspect the result, and compare it with the existing process. Pay attention to the corrections you keep making. Those corrections often show you what the system would need before it could help consistently.
As the scope and consequences grow, the testing, permissions, oversight, and operating discipline need to grow with them. Moving from a personal experiment to something colleagues may depend on is where many of these details become unavoidable.
You may find a worthwhile AI use case. You may find that a simpler automation would do the job. Either result gives you something useful to work with.
For me, the experimentation has led to a specific opportunity: help staff find and verify approved information more easily. The controlled pilot is where we begin finding out how well this implementation can serve that need.
I plan to write about the project as it develops, including the technical decisions, testing, governance, costs, and feedback that shape it. I may also turn the journey into a YouTube series. There are enough lessons here for several episodes, and I expect the pilot to give me plenty more to learn.
The first demo showed me enough to keep building. Now I want to find out what it takes to make the tool useful in practice.
Related reading
AI Agents Need Managers Too
Why project management, agile delivery, and operating discipline become more important as AI agents enter real workflows.
I Asked My AI Agent to Deploy a Website to AWS
A static website deployment to AWS somehow became Vaiyora: a convincing luxury hospitality brand with reservations, inquiries, and a suspicious amount of value creation.