I asked an AI agent to publish a post. It agreed. Then it went quiet.
The post never appeared. I only learned that when I returned and asked what had happened.
I have experienced this on two different agent platforms. I am leaving both unnamed because the issue deserves attention across the category: how delegated work is tracked, how an unresolved task becomes visible, and who is responsible for noticing.
The missing post was frustrating. Having to discover it myself exposed a larger problem.
I had delegated the action. I was still responsible for remembering the assignment, checking its status, and discovering that it had not happened.
That monitoring obligation had quietly stayed with me.
Accepting work creates an obligation
When an agent agrees to perform a task, that agreement should create a durable record of responsibility.
The record needs to survive beyond the conversation. It should identify the requested outcome, the agent responsible, the access or approval required, and when completion is expected. For an open-ended task, it should establish when the next update is due.
Otherwise, an accepted assignment can disappear into conversational history. The user remembers a commitment. The platform may have nothing that reliably distinguishes it from an ordinary exchange.
For publishing, the outcome is concrete: the post becomes visible at its intended destination. Preparing the content or attempting a tool call represents progress toward that outcome. The task remains open until publication is confirmed or another explicit outcome is recorded.
This is where governance becomes practical. Someone has to define what completion means and what happens when the system cannot establish it.
Silence is an ambiguous state
A quiet agent might be working. It might be waiting for approval. It might have lost access, encountered an error, exhausted a limit, or stopped executing.
From the user's perspective, those conditions can look identical.
That ambiguity makes silence a poor status signal. It also shifts the burden toward the person who delegated the task. They must decide how long to wait, whether to intervene, and whether another attempt could create a duplicate action.
A useful task record should make the current state visible: queued, running, waiting, blocked, completed, or failed. It should also show when that state last changed.
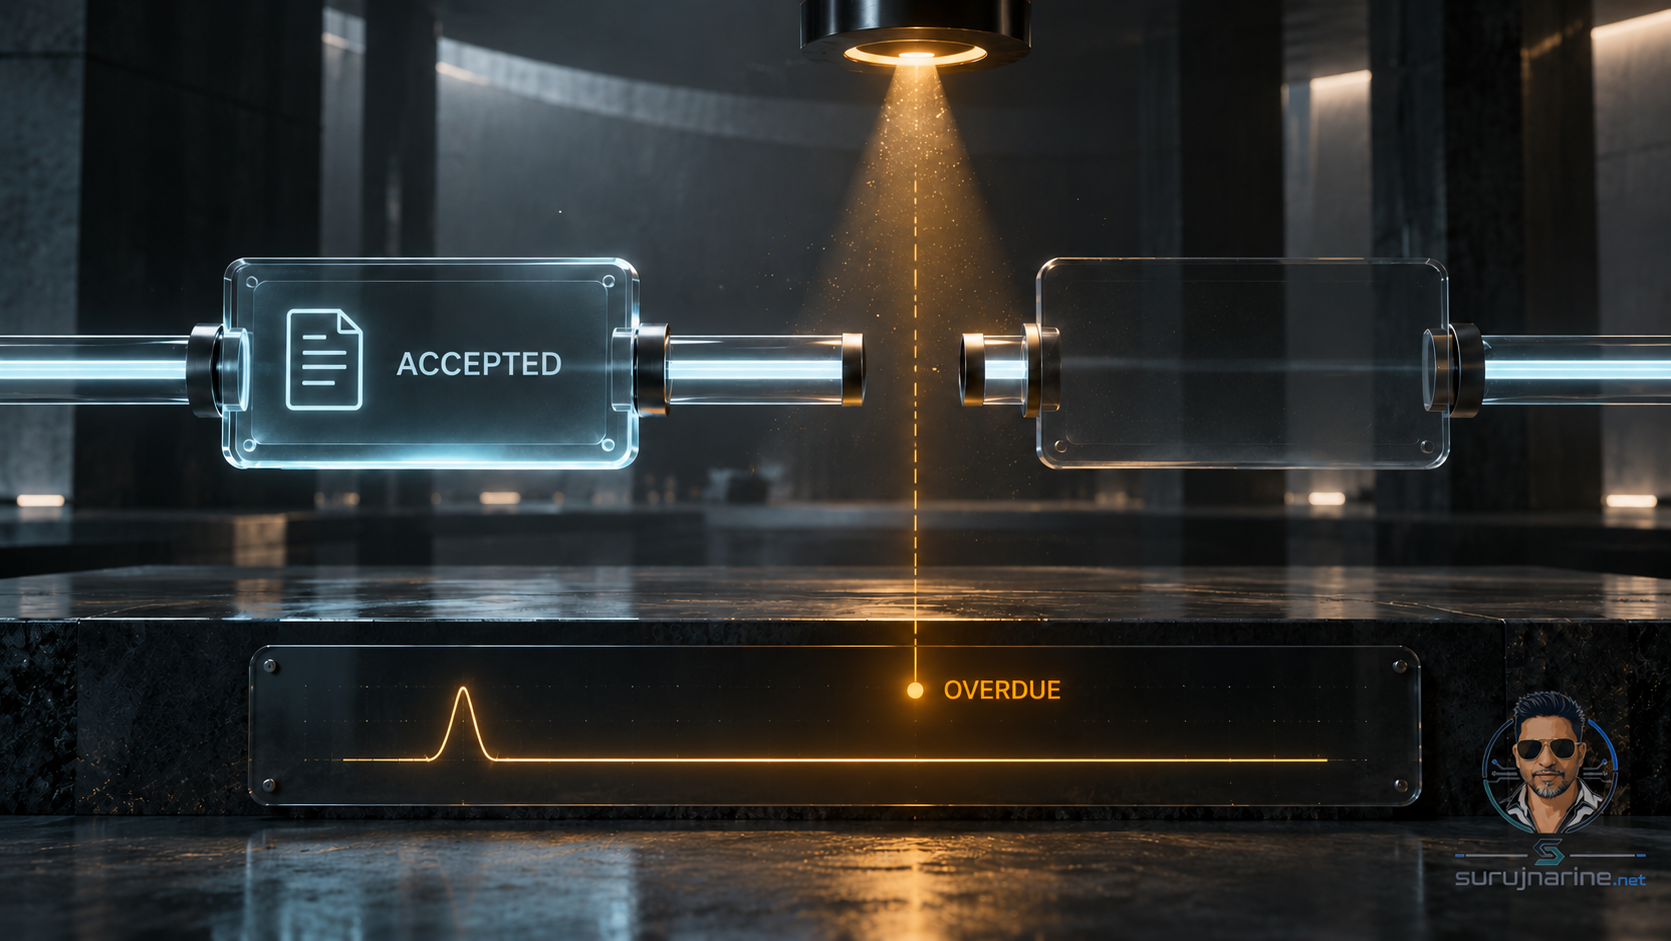
An accepted task that has exceeded its expected completion time needs attention. The platform should surface that condition without waiting for the user to ask.
Monitoring should check the outcome
Traditional service monitoring provides part of the answer. We can check whether a worker is running, whether an integration is connected, and whether requests are returning errors.
Those signals are useful, but a healthy service can still leave a task unfinished.
A publishing workflow therefore needs an outcome check. Did the expected post appear? Is there a publication identifier or a working link? Does the visible content match the intended result?
A heartbeat establishes that a component is alive. An outcome check establishes that the delegated work reached its destination.
For consequential actions, the evidence should come from the system where the action occurred. An agent's conversational account can help explain the process, but the destination provides stronger evidence of completion.
Where confirmation is unavailable, the status should preserve that uncertainty. "Submitted; publication unconfirmed" gives the user information they can act on.
The failure reporter can fail too
It is tempting to solve this by instructing the agent to report every failure.
That helps when the agent remains capable of reporting. It leaves a gap when execution stops before an update is sent.
The monitoring mechanism needs some independence from the worker performing the task. A separate component should be able to observe an overdue assignment, detect the absence of a terminal outcome, and raise an exception.
For a scheduled post, that might mean checking shortly after the expected publication time. For a longer task, it might mean detecting that no progress update has arrived within an agreed interval.
The thresholds should reflect the work. A missed publication deadline and a research task taking longer than expected require different responses. Both need a defined response.
Governance includes recovery
Once an unresolved task becomes visible, someone still has to decide what happens next.
That decision needs rules. Which failures can be retried automatically? When does the agent need renewed authorization? How does the workflow check whether an earlier attempt succeeded before trying again?
Publishing makes the duplicate-action problem easy to understand. If a request timed out after the platform accepted it, retrying blindly could produce a second post.
A recovery process should establish the destination's state, then choose the next action. Where the state remains uncertain, the uncertainty should be escalated.
An audit trail should preserve the assignment, attempts, approvals, evidence, and final disposition. That gives the user a way to understand what happened and gives the operator a way to improve the workflow.
Delegation needs a closed loop
I still see substantial value in agents that can perform real work. That value grows when I can redirect my attention with confidence.
My experience showed me where that confidence breaks down. The agents agreed to act. The work remained unfinished. Nothing brought that unresolved obligation back to my attention.
A dependable delegation system should make every accepted task traceable to an outcome. Completion needs evidence. Blocked work needs an explanation. Overdue work needs monitoring. Recovery needs an owner.
The post did not happen, and I eventually found out by asking.
The governance requirement is straightforward: the system should have made sure I knew.